Page Builders Are Great Until You Use Them for Everything

Okay, I’ll admit it. The first time I used a page builder, I felt like a wizard. Drag a box here, plop an image there, and poof—a homepage that didn’t look like a relic from 2004. I’ve spent entire weekends staring at those glossy demo templates, absolutely sure I’d never write another line of code. And honestly, for a little while, that holds up. But after years of untangling client sites that were built entirely with one of these things, I’ve hit a wall. When you use a page builder for every single thing, the cracks spread fast. I’m not telling you to delete yours in a rage. I’m just saying you need to know when to step away from the drag-and-drop.

Person working on laptop with messy desk

The Promise vs. the Reality

Page builders sell themselves as the great equalizer. No code, no developer, just your imagination and a free Saturday. That pitch is hard to resist. You watch a ten-minute video and suddenly you’re halfway through building a membership area, an online shop, a blog with slick parallax sections. The catch? That promise only carries you through the first 80% of the project. That last 20%—the weird customizations, the performance headaches, the baffling bug where a button vanishes on tablets—will eat your weekend and then ask for seconds.

What the marketing skips is the heaping pile of code these builders churn out behind the scenes. Every section you add, every module, every cute little animation tells the builder to spit out hundreds of lines of nested divs, inline styles, and JavaScript triggers. Multiply that across fifty pages and you’ve got a site that’s technically alive but sounds like it’s breathing through a straw.

The Bloat You Can’t See

Fire up your browser’s developer tools on a page-builder site and just stare at the DOM. It’s a Russian nesting doll designed by a committee. Divs wrapped in divs wrapped in more divs, all sporting class names like .elementor-element-39c8f5a or .et_pb_section_video_bg. Each one tacks on a sliver of load time. On its own, no big deal. Piled together, it’s why your site drags on mobile and earns a sad 45 on PageSpeed Insights.

I once inherited a real estate site built entirely with a popular builder. The homepage alone had 142 DOM elements just for the hero area. The slider, the text overlay, the call-to-action button, the background image—all swaddled in layers of auto-generated markup. The client couldn’t grasp why their site took eight seconds to load on a 4G connection. The builder made it dead simple to create, sure. It also made it dead simple to create a swamp.

When You Handcuff Yourself to a Single Ecosystem

Page builders lock you in. That’s not tinfoil-hat talk; it’s their business model. You build your site with Builder X, and every page, every template, every footer gets stored in Builder X’s special sauce format. Try switching to a different builder or even back to plain WordPress, and your content comes out looking like alphabet soup. Shortcodes littered everywhere, busted layouts, missing styles. You’re not swapping tools—you’re rebuilding from the ground up.

This hurts most when you’re ready for a redesign. Say you’ve used a builder for three years. Your brand has shifted, your audience has grown, and you’re craving a cleaner, quicker site. But all your content is locked inside that builder’s framework. The other path is copying and pasting every blog post, every product description, every landing page into a fresh setup. That’s not a redesign; that’s a hostage negotiation.

Plugin Conflicts and Update Anxiety

Because page builders are plugins—big, chunky ones—they have to get along with every other plugin on your site. And WordPress has no shortage of plugins. A routine security patch, a new caching tool, even a minor theme tweak can shatter your carefully styled pages. I’ve had clients email me in a cold sweat because a scheduled update made their contact form drift off-screen. The fix was rolling back the builder version and praying for a patch. That’s not how a professional site should behave.

Then you’ve got the update cycle itself. Major builder releases sometimes break things. New features deprecate old ones. A module you leaned on gets renamed or rebuilt. If you’ve built fifty pages with that module, you’ve got fifty pages to check by hand. On a plain WordPress site running the block editor and a lean theme, updates rarely cause this much drama. The core stays steady, and you decide how much complexity to pile on.
Frustrated person looking at computer screen

When Page Builders Make Sense (and When They Don’t)

I’m not a purist. I’ve used page builders for quick landing pages, event microsites, and rough prototypes. They’re brilliant when you need a one-off page with a specific look and you don’t want to wrestle custom CSS for a single campaign. They’re also a lifeline for clients who need to make minor text edits themselves but freeze up staring at the WordPress dashboard. A builder’s front-end editor can give them the guts to tweak a headline without nuking the whole layout.

The mess begins when you treat the builder as your site’s entire spine. When every page, every post, every custom post type funnels through the builder, you’ve swapped short-term convenience for long-term fragility. A smarter play is using the builder for what it actually does well—visual layouts that truly need custom columns, overlays, or interactive bits—and letting WordPress handle the rest. Blog posts, standard service pages, your about page: these can live happily in the built-in block editor, which keeps improving and doesn’t slap on a layer of proprietary shortcodes.

The Performance Tax Nobody Talks About

Let’s get into some numbers. A typical page builder tacks on anywhere from 200KB to 1MB of extra CSS and JavaScript to each page load. That’s before you’ve added a single image. On a shared hosting plan—where most starter sites live—that extra heft shoves you straight into slow-load purgatory. Google notices. Visitors notice. Study after study shows that a one-second delay in page load hacks away at conversions by about 7%. Your gorgeous builder page might be quietly torching sales just because it’s too heavy.

I ran a test on this once with a client’s site. We rebuilt their homepage from a page builder to a custom-coded template using Advanced Custom Fields and a few lines of CSS. The page weight dropped 68%, and load time plunged from 4.2 seconds to 1.1 seconds. Same design, same content, wildly different performance. The client didn’t care about the tech—they cared that their bounce rate fell 15% in the first week.

Accessibility and SEO Suffer Quietly

Page builders often spit out HTML that’s functional but semantically scrambled. Headings might jump levels because a module defaults to H2 while the section header sits at H4. ARIA labels stay empty. Images get loaded without useful alt text unless you remember to fill them in yourself. Keyboard navigation can break when the tab order doesn’t match the visual flow.

These aren’t just nice-to-haves. Accessibility slip-ups can get you sued, and messy semantics make it tougher for search engines to parse your content. Google’s algorithms are clever, but they’re not mind-readers. If your page structure is a tangle of nested divs with no logical hierarchy, your rankings can take a hit. I’ve watched sites climb several spots just by tidying up heading structure and trimming DOM depth—stuff that’s a real pain to control inside a page builder.

The Learning Curve That Doesn’t Transfer

Spend two years mastering a specific page builder, and you’ve built a skill that lives and dies inside that ecosystem. The concepts—margins, padding, responsive breakpoints—do carry over, but the interface doesn’t. If you ever want to shift to a different platform, or even just to native WordPress development, you’re back near square one. Learning basic HTML and CSS, on the other hand, is a skill you can drag anywhere. It’s more work up front, but it earns its keep forever.

I’ve talked to far too many people who call themselves WordPress experts but can’t troubleshoot a site without their favorite builder installed. That’s not expertise; that’s dependency. And when the builder company hikes its prices, gets bought out, or stops shipping updates, that dependency turns into a ticking bomb.

Person organizing sticky notes on wall for planning

A Smarter Workflow for Real Sites

So what’s the alternative? It’s not crawling back to 2010 and hand-coding every page in a text editor. It’s about being picky. Use a page builder for that complex landing page that genuinely benefits from visual control. For your core site structure—headers, footers, blog layouts, archive pages—lean on your theme’s built-in features or a lightweight block-based approach. Modern themes like GeneratePress, Kadence, or even a well-tuned Twenty Twenty-Four can handle most design needs without a builder piled on top.

For custom content types, tools like Advanced Custom Fields paired with a simple custom template give you full control without the bloat. You define the fields, your developer (or you, if you learn a little PHP) builds the template once, and then content entry is as simple as filling out a form. No drag-and-drop, no fifty nested divs, no update panic.

If you’re not ready for custom dev work, at least be strategic about your builder usage. Limit it to key pages. Audit your site’s performance regularly with tools like PageSpeed Insights or GTmetrix. Cache like crazy. And when you catch yourself fighting the builder to achieve a basic layout, stop. That’s your gut telling you the builder isn’t saving you time anymore.

Frequently Asked Questions

Are page builders bad for SEO?

Not by default, but they can stir up trouble. The extra code they pile on increases page size and load time, both known ranking signals. More to the point, their HTML output is often less semantically clear than hand-coded or block-editor output, which can make it harder for search engines to read your content structure. If you stick with a page builder, obsess a little over heading hierarchy, image alt text, and page speed.

Can I switch away from a page builder without losing my content?

It’s a mixed bag. If your content is mostly text and images, you can often copy and paste it into the block editor or a custom field setup. But any design-specific bits—columns, animations, custom spacing—will need to be rebuilt. Some builders leave behind shortcodes that turn into junk if you deactivate the plugin. The safest route is to spin up a staging site, kill the builder, and see what crumbles before you commit.

What’s the best page builder for a small business site?

There’s no single winner, but I lean toward builders that churn out cleaner code and play nicely with lightweight themes. Hunt for one that lets you disable modules you don’t use, outputs minimal inline styles, and has a track record of stable updates. Even then, use it with a light touch. The best builder is the one you don’t lean on for every pixel of your site.

Do I really need to learn code to build a good WordPress site?

Not for everything. You can build a solid, fast, maintainable site with the block editor and a quality theme, no code required. But if you want custom layouts that don’t feel bloated, or if you plan to maintain sites professionally, learning basic HTML, CSS, and a smidge of PHP will rescue you from countless hours of wrestling builder interfaces. It’s an investment that makes every future project less of a headache.

Page builders aren’t the villain. They’re tools, and like any tool, they’re brilliant for some jobs and terrible for others. The problem isn’t using them—it’s using them for absolutely everything, blind to the trade-offs. Your website matters too much to run on autopilot. Be the person who knows when to drag-and-drop and when to keep it lean.

Why Your ‘Quick and Easy’ Page Builder Is Slowing You Down

Look, I get it. You want a beautiful website without writing a single line of code, and a page builder promises exactly that. Drag, drop, done. I’ve been in your shoes more times than I can count. But after years of untangling bloated sites, sweating over mobile layouts that refuse to cooperate, and explaining to clients why their “simple” update broke the homepage, I’ve developed a pretty firm stance: using a page builder for everything is a trap. A friendly, colorful, well-marketed trap, but a trap nonetheless.

This isn’t about gatekeeping web design. It’s about making smarter choices so your site doesn’t become a slow, clunky maintenance nightmare. When you treat a page builder as the default solution for every page, every landing page, and every blog post, you’re not simplifying your life—you’re just pushing the complexity somewhere else. And it always comes back to bite you.

Frustrated person looking at laptop screen with tangled cables nearby

The Allure of the Drag-and-Drop Promise

Let’s start with what page builders do really well. They give you visual control without needing to touch a CSS file. For a small business owner launching a first website, that’s a gift. You can tweak colors, move columns, add a contact form, and see exactly what you’re getting in real time. For quick prototypes or one-off landing pages, tools like Elementor or Divi can get a decent-looking page out the door fast.

The problem starts when that becomes the building philosophy for an entire site. You’re not just designing a page; you’re stacking up shortcodes, inline styles, and nested div structures that the builder generates automatically. Every new section adds more code, more database queries, and more dependencies on the builder’s updates. What felt like freedom during the design phase turns into a chain you drag behind every page load.

I’ve seen people build entire blog post templates inside a page builder. I’m not talking about a custom archive page—I mean every single post, with a custom layout, built with the same drag-and-drop tool. That’s like using a chainsaw to slice a loaf of bread. The tool can do it, but you’re going to end up with a mess on the counter.

The Hidden Costs Nobody Talks About

1. Performance Goes Out the Window

Page builders are notorious for blowing up page size. Even a modest homepage built with a popular builder can easily load over 100 HTTP requests and several megabytes of assets, especially if you’re not meticulous about optimizing every image, font, and icon. Some builders load their entire library of widgets on every page, whether you use them or not. That means your simple About page is dragging along the code for sliders, carousels, and progress bars it never displays.

Google cares about this. Your visitors care, too—especially on mobile. If your site takes more than three seconds to load, you’re losing people. I’ve rescued sites where simply moving the blog posts out of a builder template cut the load time in half. You can’t optimize what you can’t control, and with a page builder, you’re often locked into its rendering pipeline.

Person holding a stopwatch in front of a laptop, measuring website speed

2. The Maintenance Monster

Page builders update constantly. Sometimes those updates fix bugs; sometimes they introduce new ones that rearrange your carefully placed columns. If you’ve ever opened a page you haven’t touched in six months only to find the layout shattered like a dropped vase, you know the pain.

And heaven help you if you ever decide to switch themes or—brace yourself—stop using that page builder. The content gets littered with shortcodes that the native WordPress editor doesn’t understand. You’re left with a mess of [builder_element_123] markers that mean nothing. Moving away from a page builder often means rebuilding pages from scratch, which is exactly the kind of tedious work you were trying to avoid.

3. The False Sense of Simplicity

Here’s where I get a little blunt. Page builders make you feel like a designer, but they don’t teach you anything about design. You get a panel with 40 widget options, and suddenly every page needs a countdown timer, an animated headline, and a testimonial carousel. The result is a site that looks busy, inconsistent, and frankly, amateurish.

Good web design is about restraint: consistent spacing, a clear type hierarchy, and a layout that guides the eye without shouting. When you’re working with a builder’s visual interface, it’s tempting to tweak every pixel until the page looks “perfect” on your screen, but you’re often creating a fragile layout that breaks on a slightly different viewport. The tool encourages decoration over structure.

When Page Builders Make Sense (And When They Absolutely Don’t)

I’m not saying throw your page builder in the trash. They have their place. Landing pages for a specific campaign, a temporary sales page, or a quick “coming soon” layout are reasonable uses. The key is to limit the scope. Use the builder for a handful of pages, not the entire site architecture.

Where page builders become a problem:

  • Blog posts and recurring content. Your blog should use the native WordPress editor, maybe with a lightweight block library if you need extra elements. Don’t drag the builder into every post.
  • Core site pages that rarely change. Your About page, Contact page, and Services page can live in the builder if you must, but even then, a custom-coded template or a well-configured theme will be leaner and faster.
  • Any page where accessibility matters. Many page builders produce markup that’s a nightmare for screen readers. If you’re building a site for a public institution, healthcare, or government, hand-coded semantic HTML is the only responsible choice.

Think of a page builder like a power drill. It’s brilliant for drilling holes. But if you start using it to stir pancake batter or hammer nails, you’re going to ruin the batter and bend the nails. Use the right tool for the job.

What to Do Instead

You don’t have to learn PHP from scratch. The modern WordPress block editor (Gutenberg) has come a long way, and it’s built into the core. It doesn’t leave behind the same kind of messy shortcode residue if you switch themes. For more flexible layouts, you can pair it with a lightweight theme that supports full-site editing. You’ll get visual editing without the massive overhead.

If you really need builder-like control for a few key pages, consider using a page builder only on those pages and leaving the rest of the site alone. Most major builders let you enable or disable them on a per-post-type basis. That alone can save your blog posts from the bloat.

Person working calmly at a clean, well-organized desk setup

For the long haul, I always recommend investing a little time in understanding the basics of your theme’s template system. Even knowing how to create a custom page template and drop in a few simple HTML structures can free you from the builder’s grip. It’s not as scary as it sounds, and the performance gains are immediate and measurable.

Frequently Asked Questions

Can I build a fast site with a page builder?

You can, but it takes discipline and extra work. You’ll need to be aggressive about caching, image optimization, and disabling unused builder modules. Even then, a similarly-designed custom-coded site will typically be faster because it doesn’t carry the same overhead.

What should I use for blog posts instead of a page builder?

Stick with the built-in WordPress block editor. It’s more than capable of creating engaging post layouts, and it won’t lock your content into a proprietary format. If you need extra blocks, there are plenty of lightweight block plugins that add features without the bloat.

Will I lose all my content if I switch away from a page builder?

The text content usually remains, but the layout and special formatting will break. You’ll likely see shortcode leftovers in the classic editor. It’s not a clean break, which is why it’s better to limit the builder’s use from the start rather than trying to extract yourself later.

Are some page builders better than others for performance?

Yes, but even the leanest ones add more weight than a well-coded theme. Oxygen and Bricks are often mentioned as more developer-friendly options with cleaner output, but they still require careful setup. The core issue remains: the more pages you build with them, the more you depend on that tool.

What matters is that your site serves your visitors and doesn’t exhaust your patience. Page builders aren’t evil. They’re just overused. When you reserve them for the occasional special page and build the rest of your site on a solid, lightweight foundation, you get the best of both worlds: creative control where you need it and a site that loads fast, ranks better, and doesn’t keep you up at night worrying about the next update.

A Practical Guide to WordPress Hosting for Non-Technical Users

So you want to start a WordPress site, and someone told you that you need “hosting.” What does that even mean? If you’re not a developer, the world of web hosting can feel like walking into a conversation halfway through. There’s jargon everywhere, pricing that doesn’t always make sense, and a seemingly endless list of providers all claiming to be the best.

I’m Simone, and I’ve spent years helping people just like you figure out this exact problem. The good news? WordPress hosting isn’t as complicated as it sounds once you strip away the marketing fluff. This guide will walk you through what you actually need to know, without the technical overload.

Laptop with WordPress website on screen

What Is WordPress Hosting, Really?

Think of hosting as renting space on a computer that stays on 24/7. That computer (called a server) stores all your website files and delivers them to visitors when they type in your web address. Without hosting, your WordPress site has nowhere to live.

WordPress hosting simply means the hosting provider has set up their servers specifically to run WordPress well. This usually includes pre-installed WordPress, automatic updates, and server configurations that make your site load faster and stay secure.

You can run WordPress on regular hosting, but WordPress-specific hosting takes a lot of the guesswork out of the setup process. For non-technical users, that’s a real advantage.

Types of WordPress Hosting Explained

Not all hosting is created equal. Here are the main types you’ll encounter, broken down in plain language.

Shared Hosting

This is the most affordable option, usually ranging from $2 to $10 per month. Your site shares a server with potentially hundreds of other websites. Think of it like living in an apartment building — you share the plumbing, the electricity, and the hallways.

Pros: Cheap, easy to set up, good for beginners.
Cons: Can be slow if other sites on your server get a lot of traffic. Security risks are slightly higher because you’re sharing space with other sites you don’t control.

Managed WordPress Hosting

The provider handles all the technical maintenance — updates, security scans, backups, and performance tuning. You just focus on your content. Plans typically run $15 to $50+ per month.

Pros: Very hands-off, strong security, fast load times, good support.
Cons: More expensive, and some providers limit which plugins you can use.

Server room with blue lighting

VPS (Virtual Private Server) Hosting

You still share a physical server, but you get a guaranteed slice of resources that nobody else can touch. It’s like owning a condo instead of renting an apartment. Prices range from $20 to $100+ per month.

Pros: More consistent performance, better security, room to grow.
Cons: Requires more technical knowledge, or you need to pay for a managed layer on top.

Dedicated Hosting

An entire server just for you. This is overkill for most small to medium sites and costs $100+ per month. Unless you’re running a massive e-commerce store or a high-traffic publication, you can skip this for now.

Key Factors to Consider When Choosing Hosting

With those categories in mind, here’s what actually matters when you’re comparing providers.

Uptime Guarantee

Uptime is the percentage of time your site is accessible. Look for at least 99.9% uptime. A few providers even offer 99.99%. That difference sounds small, but 99.9% means roughly 8.7 hours of downtime per year, while 99.99% means less than an hour. If your site makes money, every minute of downtime costs you.

Page Load Speed

Slow sites lose visitors. According to Google’s research, 53% of mobile users leave a page that takes longer than 3 seconds to load. Ask providers about their average load times, or check independent reviews that test this.

Customer Support

For non-technical users, this might be the single most important factor. Look for 24/7 live chat or phone support. Test it yourself — send a pre-sale question and see how fast and helpful the response is. If you can only reach support via email tickets that take 24 hours, that’s a red flag.

Backups

Does the provider offer automatic daily backups? Can you restore your site with one click if something goes wrong? Don’t assume backups are included. Some budget hosts charge extra for them or only do weekly backups.

SSL Certificate

An SSL certificate gives your site that little padlock icon in the browser and enables HTTPS. Most good WordPress hosts now include a free SSL certificate (usually Let’s Encrypt). If a provider charges extra for this, that’s a warning sign.

Person working on website dashboard

Scalability

Your site might be small now, but what happens if traffic spikes? Can you upgrade your plan easily without migrating to a new server? Good providers let you scale up with a few clicks. Avoid ones that require a full migration just to move from their basic plan to their mid-tier option.

Common Mistakes Non-Technical Users Make

I’ve seen these same mistakes over and over. Learn from them instead of making them yourself.

1. Choosing the cheapest plan without reading the fine print. That $1.99/month deal often jumps to $8-12/month after the first term. Renewal rates matter more than introductory prices. Always check what you’ll actually pay in year two.

2. Ignoring bandwidth and storage limits. Most entry-level plans offer enough for a blog or small business site, but if you plan to host video files or have thousands of large images, you’ll hit limits faster than you think.

3. Not testing the support team before committing. The cheapest host in the world isn’t worth it if you can’t reach anyone when your site goes down at 11pm on a Friday.

4. Paying for features you won’t use. If you’re running a personal blog, you probably don’t need a dedicated IP address, premium DNS, or staging environments. Don’t let upselling push you into a plan that exceeds your actual needs.

How to Migrate If You Picked the Wrong Host

Maybe you’re reading this because you already have hosting and it’s not working out. That’s okay — migrating WordPress sites is much easier than it used to be.

Many reputable hosts offer free migration as a perk for switching. You give them access to your current site, and they handle moving all your files and database. The whole process typically takes 24 to 48 hours, and your site stays live throughout.

If your new host doesn’t offer free migration, you can use a plugin like Duplicator or All-in-One WP Migration to package your site and move it yourself. It’s not as scary as it sounds — most plugins walk you through the process step by step.

A Quick Word on Pricing Reality

Hosting companies are notorious for promotional pricing. That $2.95/month deal usually requires a 3-year commitment paid upfront, and the renewal rate might be $9.95/month. Here’s a rough breakdown of what you should actually expect to pay:

  • Shared hosting: $3-10/month (introductory), $6-15/month (renewal)
  • Managed WordPress: $15-50/month (pricing usually stays stable)
  • VPS hosting: $20-100/month (varies widely based on resources)

Always calculate the long-term cost, not just the first year. A slightly more expensive plan that includes backups, SSL, and good support often works out cheaper than a barebones plan where you pay for add-ons.

The WordPress.org team maintains a list of recommended hosting providers that’s a solid starting point for your research.

FAQ

Do I need WordPress hosting, or can I use any web hosting?

You can absolutely run WordPress on standard web hosting. WordPress has modest server requirements — it needs PHP, MySQL or MariaDB, and a web server like Apache or Nginx. That said, WordPress-specific hosting saves you setup time and ongoing maintenance effort. If you’re not comfortable installing WordPress yourself or managing updates, WordPress hosting is worth the extra cost.

What’s the difference between WordPress.com and self-hosted WordPress?

WordPress.com is a hosted service where your site lives on their platform — it’s like renting a furnished apartment where the landlord handles all maintenance. Self-hosted WordPress (from WordPress.org) is free software you install on your own hosting account, giving you full control but also full responsibility. Self-hosted is the way to go if you want complete freedom over your site’s design, plugins, and monetization.

How much traffic can shared hosting handle?

A decent shared hosting plan typically handles 10,000 to 25,000 monthly visitors without issues. Once you exceed that, you may notice slower load times or occasional downtime. If your site is growing past 25,000 visitors per month, it’s time to look at managed WordPress hosting or a VPS.

Should I buy my domain name from my hosting provider?

It’s convenient, but not always the cheapest option. Hosting providers often include a free domain for the first year, which is nice. However, renewal rates for domains through hosts can be higher than dedicated registrars like Namecheap or Domain.com. There’s no technical disadvantage either way — it’s purely a pricing and convenience decision.

Final Thoughts

Choosing WordPress hosting doesn’t require a computer science degree. Start by being honest about your needs: a small personal blog has different requirements than a business site that needs to be online every second of every day. Pick a provider with solid support, fair renewal pricing, and a clear upgrade path. You can always switch later, and most good hosts make that process painless.

Don’t overthink it. Get started, learn as you go, and upgrade when your traffic demands it. The best hosting for you is the one that lets you focus on creating content instead of troubleshooting servers.

A Practical Guide to WordPress Hosting for Non-Technical Users

You want a WordPress site. You’ve heard you need “hosting.” And now you’re staring at a wall of options, each one promising the moon for $2.99 a month. I get it — hosting is one of those topics that sounds way more complicated than it actually is. Let’s cut through the noise.

I’m Simone, and I’ve helped plenty of people who don’t know a PHP error from a parking ticket get their WordPress sites running smoothly. This guide is for you if you just want a site that works, loads fast, and doesn’t cost a fortune.

Person working on a laptop at a desk

What WordPress Hosting Actually Is

Think of hosting as renting space on a computer that’s always on and always connected to the internet. That computer (called a server) stores your website files and serves them to visitors when they type in your domain name. That’s it. No mystery required.

WordPress hosting just means the server is set up to run WordPress specifically. Since WordPress powers over 40% of all websites, most hosting companies offer WordPress-optimized plans. Some even manage the technical stuff for you — updates, security, backups — so you can focus on your content.

The Four Main Types of WordPress Hosting

Here’s where most people get overwhelmed. Let me break down each type in plain language.

1. Shared Hosting

Your site shares a server with dozens or hundreds of other sites. It’s like living in an apartment building — you split costs, but you also share resources. If your neighbor’s site gets a traffic spike, your site might slow down.

Best for: New sites, personal blogs, small business sites with under 5,000 monthly visitors.

Typical cost: $2–$10/month

Watch out for: Renewal prices that jump dramatically after the first term. That $2.99/month deal? It might become $9.99/month at renewal.

2. Managed WordPress Hosting

This is shared hosting’s smarter cousin. The hosting company handles WordPress updates, daily backups, security scanning, and speed optimization. You get better performance and support from people who actually know WordPress.

Best for: Business sites, growing blogs, anyone who doesn’t want to deal with technical maintenance.

Typical cost: $20–$50/month

Watch out for: Some managed hosts limit plugins they consider “slow” or “insecure.” If you rely on a specific page builder or caching plugin, check their allowed list first.

Team collaborating around a computer

3. VPS Hosting

Virtual Private Server hosting gives you a dedicated slice of a server’s resources. It’s like owning a townhouse — you have guaranteed resources, but you’re still on shared property. You’ll often need to manage the server yourself or pay extra for a managed VPS.

Best for: Sites with 25,000+ monthly visitors, WooCommerce stores, or sites needing custom server configurations.

Typical cost: $15–$80/month (unmanaged) or $40–$150/month (managed)

Watch out for: If you pick an unmanaged VPS, you’re on the hook for server security, software updates, and troubleshooting. Not ideal if the command line scares you.

4. Dedicated Hosting

You get the entire server to yourself. It’s powerful, expensive, and almost certainly more than you need right now.

Best for: Enterprise sites, sites with 100,000+ monthly visitors, or sites handling sensitive data that requires isolated environments.

Typical cost: $100–$500+/month

Watch out for: Unless you have a system administrator on your team, managed dedicated hosting is the only realistic option here. And it’s pricey.

What Actually Matters When Choosing a Host

Forget the marketing bullet points. Here’s what you should actually care about:

Uptime

Your site should be available 24/7. Look for hosts that guarantee at least 99.9% uptime. Anything below that means your site could be down for over 8 hours a year — that’s lost visitors, lost sales, and lost credibility.

Speed

Page load time directly affects your search rankings and whether visitors stick around. According to Google’s web.dev resources, sites loading in under 2.5 seconds provide a good user experience. Ask hosts about their server response time (TTFB) — aim for under 200ms.

Support Quality

This is the big one for non-technical users. When something breaks at 11 PM on a Friday, you want someone who actually helps. Look for:

  • 24/7 live chat or phone support (not just email tickets)
  • WordPress-specific knowledge — not generic script readers
  • A reputation for fast response times

Check real user reviews on independent sites, not just the testimonials on the host’s homepage.

Backups

Things go wrong. Plugins conflict, updates break things, and sometimes you just make a mistake you can’t undo. Daily backups with easy restore options are non-negotiable. Many managed WordPress hosts include this; shared hosts often charge extra.

SSL Certificate

Your site needs HTTPS — it’s required for security, and browsers will flag your site as “not secure” without it. Most decent hosts include a free SSL certificate (Let’s Encrypt). If a host charges extra for SSL, that’s a red flag.

Room to Grow

Can you upgrade your plan easily when your traffic grows? Switching hosts is a hassle. Starting with a host that has clear upgrade paths (shared → managed → VPS) saves headaches later.

Server room with blinking lights

Red Flags to Avoid

Some hosting companies use tactics that should make you think twice:

  • Unlimited everything: There’s no such thing as unlimited resources. Read the fine print — “unlimited” always has fair use limits, and you’ll hit them when your site grows.
  • Super-long billing cycles: Three-year upfront payments lock you in. If the host is bad, you’re stuck. Start with monthly or annual billing until you trust them.
  • No refund policy: Reputable hosts offer money-back guarantees (usually 30 days). No refund policy means they don’t stand behind their service.
  • Slow support responses: Test support before you commit. Send a pre-sale question and see how long they take to reply. That’s a preview of your future experience.

A Quick Decision Framework

Still unsure? Here’s a simple way to decide:

If you’re starting a new site or blog: Go with managed WordPress hosting. Yes, it costs more than bare-bones shared hosting. But the time you save on updates, security, and troubleshooting is worth every penny. Companies like SiteGround, DreamHost, and Pressable offer solid entry-level managed plans.

If you’re on a tight budget: Shared WordPress hosting from a reputable provider works fine for low-traffic sites. Just be prepared to handle more technical tasks yourself, and set up a backup solution immediately.

If you’re running a WooCommerce store: Managed WordPress hosting with e-commerce support. Stores can’t afford downtime or slow checkout pages. The extra cost pays for itself in avoided lost sales.

If your existing site gets 25,000+ monthly visitors: It’s time to look at managed VPS hosting. Your shared or entry-level managed plan is probably struggling under the traffic.

Migrating to a New Host

Already have a host but need to switch? Most managed WordPress hosts offer free migration. They’ll move your entire site — files, database, the works — for you. This alone is a reason to choose managed hosting if you’re not technical.

If your new host doesn’t offer migration, use a plugin like Duplicator or All-in-One WP Migration. These packages your entire site into a file you can upload to the new host. It’s not as scary as it sounds — most plugins walk you through it step by step.

Always test your site on the new host before pointing your domain there. Most hosts give you a temporary URL for testing. Check every page, run a speed test, and make sure forms and checkout work before going live.

Frequently Asked Questions

Do I really need WordPress-specific hosting, or will any hosting work?

Technically, any hosting that meets WordPress’s minimum requirements will run the software. But WordPress-specific hosting saves you time and headaches. The server is pre-configured for WordPress, support staff understand the platform, and security is tuned for common WordPress vulnerabilities. For non-technical users, WordPress-specific hosting is absolutely worth the small premium.

What’s the difference between WordPress.org and WordPress.com hosting?

WordPress.com is a hosted service — they handle the hosting for you, but you’re limited in what plugins and themes you can use (on lower plans). WordPress.org is the self-hosted version where you pick your own host and have full control. When people talk about “WordPress hosting,” they mean hosting for the WordPress.org version. This guide focuses on self-hosted WordPress because it gives you the flexibility to grow your site however you want.

How much traffic can shared hosting handle before I need to upgrade?

There’s no single answer because it depends on your site’s size, how many plugins you use, and whether you have caching set up. As a rough guide: if you’re getting 5,000–10,000 monthly visitors and your site starts feeling slow in the admin area, or if your host sends you “resource limit reached” warnings, it’s time to upgrade. Don’t wait until your site crashes during a traffic spike — move proactively.

Should I buy hosting and my domain from the same company?

It’s convenient, but I recommend keeping them separate. If your host has problems or you want to switch, you don’t want your domain held hostage. Buy your domain from a dedicated registrar (like Namecheap or Domain.com) and point it to your host. It adds one small step during setup but gives you more freedom later.

Final Thoughts

WordPress hosting doesn’t have to be confusing. Start with what fits your current needs and budget. Pick a host with good support because you will need help at some point. Don’t overpay for resources you won’t use, but don’t cheap out so much that your site is slow or constantly down.

The best hosting plan is the one that lets you focus on building your site instead of worrying about server configuration. Start there, upgrade when you need to, and don’t overthink it.

Why I Think Most WordPress Sites Launch With Too Many Plugins

The Plugin Pile-On Problem

I’ve launched dozens of WordPress sites over the years, and I’ve reviewed hundreds more. There’s a pattern I keep seeing, and it’s not a good one: people installing twenty, thirty, sometimes even fifty plugins before their site goes live. I get it—plugins are tempting. They promise quick solutions for every feature you might want. But here’s the reality: most WordPress sites launch with far too many plugins, and it causes problems that don’t show up until it’s too late.

Person working on WordPress site at desk

Why We Gravitate Toward Plugins

Let’s be honest—plugins make us feel productive. You need SEO functionality? Install Yoast. Contact form? Drop in Contact Form 7. Social sharing? Add a sharing plugin. Before you know it, you’ve got a plugin for every single feature, and your dashboard looks like a software store exploded inside it.

The WordPress plugin repository has over 59,000 free plugins. That’s not a typo. With that many options, the temptation to keep adding functionality is real. Each plugin seems small and harmless on its own. A caching plugin here, a security plugin there, maybe a page builder and a couple of widgets—suddenly you’re staring at a plugin list that’s longer than your grocery list.

I fell into this trap myself on my first few sites. I wanted every bell and whistle because I thought that’s what a “professional” site needed. Spoiler: it doesn’t. Professional sites need to work well, load fast, and stay secure. Too many plugins work against all three of those goals.

The Real Cost of Plugin Overload

Performance Takes a Hit

Every plugin you activate loads code on your site. Sometimes it’s just a small function, but often it’s JavaScript files, CSS stylesheets, database queries, and external requests. These add up faster than you’d expect.

I recently audited a client’s site that was loading in eight seconds. Eight. After removing seven unnecessary plugins and consolidating functionality, load time dropped to under three seconds. Same design, same content—just fewer plugins fighting for attention.

The relationship between site performance and user experience is well-documented. Slow sites lose visitors, rank lower in search results, and convert at worse rates. Plugins are often the biggest culprit behind sluggish WordPress sites.

Computer screen showing website code

Security Vulnerabilities Multiply

Here’s something most people don’t think about: each plugin is another potential attack vector. According to WPScan’s vulnerability database, the majority of WordPress security issues come from plugins, not core WordPress files. When you install thirty plugins, you’re trusting thirty different development teams to write secure code and keep it updated.

That’s a lot of trust to hand out blindly.

Abandoned plugins are especially dangerous. Developers stop maintaining them, security patches never arrive, and vulnerabilities go unaddressed. The more plugins you run, the higher the chance that at least one of them is abandoned or insecure.

Maintenance Becomes a Nightmare

Updates are a fact of WordPress life. Core updates happen regularly, and plugin updates should follow. But when you have thirty plugins, you’re dealing with thirty potential compatibility issues every time WordPress releases a major update.

I’ve seen sites break after updates because two plugins conflicted. The site owner couldn’t figure out which plugin caused the problem, and debugging became a frustrating process of deactivating plugins one by one. That’s wasted time and, for client sites, wasted money.

What You Actually Need at Launch

Let me be direct: most sites launching on WordPress need fewer than ten plugins. I’m not being arbitrary here. Think about what a new site genuinely requires to function:

  • Security—one solid security plugin
  • SEO—one SEO plugin
  • Performance—one caching or optimization plugin
  • Forms—one form plugin
  • Backups—one backup solution

That’s five. Maybe you add a page builder if your theme doesn’t have one built in, or a specific integration your business requires. But we’re still under ten. Everything else is a want, not a need.

The “Just in Case” Trap

The biggest reason people over-install plugins? “I might need this later.” This is the same thinking that leads to cluttered garages and overstuffed closets. You install a Google Analytics plugin, a maintenance mode plugin, three different gallery plugins, and a coming-soon page—all before you have any traffic to analyze or content to display.

Install what you need when you need it. A plugin you might use someday is just dead weight on launch day.

Minimalist workspace setup

How to Audit Your Plugin List Before Launch

If you’re getting ready to launch a WordPress site, take thirty minutes to run through this process:

  1. List every active plugin and write down exactly what functionality it provides.
  2. Ask yourself: “Does my site need this functionality on day one?” If the answer is no, deactivate and delete it.
  3. Check for overlap. Are two plugins providing similar functionality? Pick one and remove the other.
  4. Consider alternatives. Can your theme handle this without a plugin? Can you add a small code snippet instead of installing a whole plugin for one feature?
  5. Research each remaining plugin. Is it actively maintained? When was the last update? How many active installs does it have?

This process is simple but eye-opening. Most people I walk through this with end up cutting their plugin count by at least a third.

When More Plugins Might Make Sense

I’m not anti-plugin. Plugins are one of WordPress’s greatest strengths. There are legitimate reasons to run a larger number:

  • E-commerce sites often need WooCommerce plus several extensions
  • Membership sites may require multiple specialized plugins
  • Enterprise or large-scale sites with complex requirements

The key word here is “need.” If your site genuinely requires twenty plugins because of its specific functionality, that’s different from installing twenty plugins because you clicked “Install” every time you saw a feature you liked.

Even then, I’d encourage looking for multipurpose plugins or all-in-one solutions that can replace several single-function plugins. One well-built plugin that handles five features is better than five plugins handling one feature each.

FAQ

How many plugins is “too many”?

There’s no magic number. A well-maintained site with twenty carefully chosen, actively updated plugins can run better than a site with eight neglected, poorly coded plugins. That said, if you’re launching with more than fifteen plugins, you should probably reevaluate whether you genuinely need all of them. For most new sites, keeping it under ten is a reasonable and achievable goal.

Should I worry about inactive plugins?

Yes. Inactive plugins still pose security risks if they have vulnerabilities, and they clutter your installation. If you’re not using a plugin, delete it. You can always reinstall it later if you need it. There’s no reason to keep deactivated plugins sitting around.

Can I use code snippets instead of plugins for small features?

Absolutely, and I recommend it when possible. Simple functions like removing the WordPress version number, changing excerpt length, or disabling comments on certain post types can be handled with a few lines of code in your theme’s functions file or a code snippets plugin. This approach keeps your plugin count lower and gives you more control over your site’s functionality.

Final Thoughts

Launching a WordPress site with too many plugins is like packing for a weekend trip with three suitcases. You’re carrying weight you don’t need, and it slows everything down. Start lean. Add plugins thoughtfully as your site grows and your needs become clear. Your visitors, your security, and your future self will thank you.

Plugins should serve your site, not clutter it. The next time you’re about to click “Install Now,” pause and ask: do I need this right now, or am I just adding baggage? That simple question can save you from the plugin pile-on that derails so many WordPress launches.

Rust in the Linux Kernel at Scale: Two Years of Merge Commits Later, What the Kernel Mailing List Drama Actually Tells Us

The Numbers Tell a Story of Acceleration, Not Speculation

When Rust support merged into the Linux kernel in late 2022 as part of version 6.1, the community was handed something unprecedented: a systems programming language with fundamentally different memory safety guarantees sitting alongside forty years of C code. The initial footprint was modest by design. We’re talking roughly 13,000 lines of Rust code, most of it foundational scaffolding and abstraction layers that no one outside the core maintainers fully understood yet. That was deliberate caution, and it was warranted.

Fast forward to early 2026, and we’re looking at over 600,000 lines of Rust code spread across drivers, filesystem abstractions, and core subsystem bindings. That’s not linear growth. That’s exponential acceleration. The trajectory matters more than any single snapshot because it tells us something about how the kernel community has moved from theoretical interest to practical deployment. The skeptics haven’t gone anywhere, but neither have the contributors, and the latter group has grown considerably.

What’s particularly notable is where this code lives. These aren’t toy modules or experimental side projects. The Nova GPU driver for NVIDIA’s open-source firmware is the highest-profile all-Rust driver effort to date, and Linus Torvalds confirmed in a December 2025 kernel mailing list post that contributions of this caliber have accelerated. That’s the kind of signal that matters. When the ecosystem’s most complex driver subsystems start shipping in Rust, you’re no longer watching an experiment. You’re watching a migration.

Memory Safety Has an Empirical Body Count

The original argument for Rust in the kernel was always philosophical: ownership models prevent entire classes of bugs at compile time rather than chasing them through fuzzing and code review. But philosophy doesn’t fund security patches or convince maintainers to adopt unfamiliar tools. Data does.

A 2025 study from the University of Waterloo analyzed 150 kernel CVEs spanning 2020 through 2024. The researchers categorized each vulnerability and found that 67 percent fell into memory safety buckets that Rust’s ownership model structurally prevents. That’s not a marketing claim. That’s an audit of actual kernel vulnerabilities in the wild. If you took those same CVEs and rewrote the affected code in Rust today, two-thirds of them would never compile in the first place. The bugs wouldn’t exist to be exploited.

That empirical weight has shifted something real in how the conversation happens on the kernel mailing list. The debate is no longer whether memory safety matters. It’s moved to the harder, more interesting question: at what cost does safety come, and is that cost acceptable for specific kernel subsystems?

The Android Case Study: Where Theory Met Production at Scale

Google’s Android team released a blog post in early 2025 that functionally settled something for a large slice of the systems programming world. The proportion of new Android OS code written in memory-safe languages reached 77 percent. Rust accounts for the majority of systems-level additions. More importantly, Google Security Blog on memory safety in Android reported that memory safety vulnerabilities in Android dropped to below 24 percent of total CVEs for the first time. That’s a concrete outcome from a concrete strategy executed across a codebase touching billions of devices.

This isn’t laboratory data. This is what happens when you actually ship memory-safe languages at scale and measure what breaks and what doesn’t. The fact that Android is tracking this metric publicly and seeing measurable improvement is exactly the kind of evidence that moves institutional needles. Other vendors watched that. Other maintainers watched that. The kernel maintainers absolutely watched that.

The corollary matters: Android didn’t rewrite everything in Rust overnight. They were surgical about it. They picked the subsystems with the highest vulnerability density and the lowest tolerance for risk, then moved those first. The kernel has been following roughly the same playbook, though more slowly and with considerably more friction from the C maintainer guard.

The Abstraction Penalty: Where Theory Meets Reality

Late 2025 brought a pivot in the discussion worth paying attention to. Ted Ts’o, a veteran C kernel maintainer with decades of credibility, posted a detailed technical critique on the kernel mailing list arguing that Rust’s abstraction layers were creating hidden performance regressions in I/O paths. More pointedly, he argued that standard benchmarks weren’t catching the regressions because the slowdowns were subtle and contextual, only showing up under specific workload patterns. This wasn’t FUD. This was a maintainer saying: I’ve read the code, I understand the compiler output, and there’s a real cost here that we’re not properly accounting for.

That criticism is precisely the kind of signal worth taking seriously. It’s not an argument that Rust doesn’t belong in the kernel. It’s an argument that the abstraction layers being built to make Rust ergonomic for kernel development are sometimes solving the wrong problem, or solving it in ways that trade off performance characteristics. That’s not a reason to stop. It’s a reason to dig deeper into the specific abstractions and understand what they’re really doing under the hood.

This is where the mailing list drama becomes actually useful instead of just noise. The conversation has matured enough that people aren’t arguing about whether Rust is theoretically better. They’re arguing about specific trade-offs in specific subsystems. That’s the conversation you want to see.

What the Next Two Years Signal About the Kernel’s Future

The trajectory from 13,000 lines to 600,000 lines suggests that Rust in the kernel isn’t going away. It also suggests Rust won’t become the dominant language everywhere. The kernel will likely end up in a hybrid state where new subsystems with high safety requirements use Rust as the default but mature, stable subsystems written in C remain mostly as-is. That’s not a failure of the Rust transition. That’s how pragmatic large systems actually evolve.

What we can reasonably forecast is that the vulnerability metrics will matter more than the ideology. If the Waterloo study holds up and the Android data continues trending the right direction, the case for Rust gets stronger, not because Rust advocates got better at arguing, but because the evidence accumulated. The Linux kernel tends to follow evidence with a three-to-five-year lag. That timeline puts us right in the window where we should expect serious expansion of Rust in security-critical driver subsystems.

For people actually working with the kernel, the implication is clear: Linux kernel Rust documentation is no longer optional reading. It’s not a required career skill yet, but it’s moving in that direction. The question isn’t whether you’ll need to know Rust to contribute to the kernel in five years. The question is which subsystems will require it first.

The mailing list drama, the abstractions, the benchmark debates, the security metrics, the corporate adoption: they all point to something coherent. The kernel is in the middle of a genuine technical transition. It’s messier than anyone predicted, slower than Rust advocates hoped, and moving more decisively than skeptics expected. That’s how real institutional change actually happens.

Salt Typhoon’s Reckoning: What Engineers Need to Build When Federal Mandates Hit in 2026

The Year We Stopped Pretending Legacy Systems Were Secure

When the FBI and CISA confirmed in late 2024 that Chinese state-sponsored actors had maintained access inside at least nine major US telecom carriers for over a year, something shifted in how we talk about network security. This wasn’t a theoretical exercise anymore. It wasn’t a breach that affected payment cards or consumer data. These were the pipes. The actual infrastructure that carries voice, data, and every digital communication Americans depend on. The intrusion, attributed to a group tracked as Salt Typhoon, exposed something that engineers like me have known for years but couldn’t quite articulate in ways that moved budgets: our telecom networks had been operating under security assumptions built for a different era.

What made this breach particularly instructive wasn’t just the scale, but the method. According to the CISA Salt Typhoon advisory, the attackers didn’t zero-day their way in. They exploited legacy Simple Network Management Protocol configurations that should have been decommissioned years ago. They found unpatched edge devices from vendors like Cisco and Fortinet that had security updates sitting on shelves. They moved freely because network segmentation didn’t exist where it mattered most. In other words, they won because we let them win.

Understanding What Actually Broke and Why It Matters for Your Next Build

Let’s talk specifics, because that’s where clarity lives. Cisco disclosed in November 2024 that Salt Typhoon actors exploited CVE-2023-20198 in IOS XE, a vulnerability with a perfect 10.0 CVSS score. Here’s the part that should make every engineer uncomfortable: patches existed for over a year before anyone confirmed the exploitation was actually happening in production environments. A year. That gap between patch release and confirmed active exploitation tells you something important about how we’ve been managing network infrastructure. We’ve treated “the patch exists” as equivalent to “we’re secure,” when what we’ve actually been doing is playing roulette with the odds tilted sharply against us.

The attack vectors themselves read like a checklist of architectural decisions from 2003. SNMP running without proper authentication. Out-of-band management interfaces accessible from places they shouldn’t be. Network segments that trusted each other by default. Device firmware that never got updated because the change window was scary. If you’re building network-adjacent systems today, these aren’t abstract concerns. These are the patterns you need to deliberately build against.

A February 2025 Mandiant report on organizations remediating after Salt Typhoon found something sobering: 73 percent of affected carriers needed a complete architectural overhaul of their carrier-grade network management interfaces. This wasn’t patching. This wasn’t running a firmware update and moving on. This was rip-and-replace work. The average remediation cost per carrier exceeded 47 million dollars. That number matters because it’s not just financial. It’s a signal about how fundamentally we underestimated what happens when the foundations crack.

The Federal Mandate That Changes Everything Starting in 2026

Here’s where your work intersects with regulation. In January 2025, the FCC issued new cybersecurity rules under Section 105 of the Communications Act. These rules require telecommunications carriers to submit annual cybersecurity risk management plans. Read that carefully. Not optional security audits. Not advisory guidelines. Mandatory, documented plans reviewed by federal agencies. This is the first FCC mandate of its kind, and it’s not going away.

What this means for engineers building network-adjacent systems is straightforward: the security architecture you’re designing now needs to anticipate audit-readiness in 2026. The systems you’re deploying need to be documentable. Every trust boundary needs to be intentional. Every access point needs to have a reason that can be explained to someone who isn’t an engineer. The vague zones where “we assume the network is trusted” need to become explicit policies.

Visit the FCC cybersecurity rulemaking proceeding if you want to see the actual language. The mandate covers incident response timelines, supply chain risk management, and vulnerability disclosure procedures. These aren’t theoretical frameworks. They’re requirements that will affect how you architect systems, how you test them, and how you hand them over to operations.

Building for 2026: Where to Actually Start

If you’re new to this space or reconsidering how you’ve been building systems, don’t let the scale of the problem paralyze you. The Salt Typhoon breach didn’t happen because engineers were stupid. It happened because the incentives were misaligned and the complexity kept growing faster than our ability to secure it. You can change that in your own work right now.

Start where the vulnerability actually existed: network management interfaces. If your system manages other systems on a network, assume that interface is attractive to attackers. Design it as if it will be exposed. Use strong authentication. Implement mutual TLS. Encrypt everything in motion and at rest. Log comprehensively. The logs aren’t just for compliance. They’re your evidence trail if something goes wrong. This is the foundational layer.

Next, think about segmentation. Every system you build should operate on the principle of least privilege, communicating only with what it actually needs to communicate with. This sounds obvious until you’re on a call with operations and they say “we need device X to be able to reach all of Y for troubleshooting.” That conversation is where security gets negotiated away. Have it early. Document the decision. Make it explicit that you’re accepting a risk because the operational need is real.

Third, and I say this from experience: patch management isn’t a checkbox. It’s an architecture decision. You need to design systems so that patches can actually be applied without causing cascading failures. That means redundancy, gradual rollouts, and testing updates in environments that look like production. The vendors will release patches. The question is whether your system is designed in a way that lets you actually use them.

The Conversation We Should Be Having Now

What Salt Typhoon exposed wasn’t a flaw in engineering capability. It exposed a gap between what we know we should be doing and what we’ve been incentivized to do. Security was treated as an additive layer, something you bolt on when regulators force you to. The FCC mandate is saying that’s not sufficient anymore. And honestly, it shouldn’t have been.

If you’re building systems that touch telecom infrastructure, or any critical infrastructure, the mandate coming in 2026 isn’t a threat. It’s permission. It’s your cover to do the work the right way, the thing you can point to when someone pushes back on building for security rather than just for feature velocity.

The question now is what you’re going to build differently. What architectural patterns are you going to implement? How are you going to design for auditability without making the system brittle? I’d genuinely like to hear what you’re thinking. The work ahead isn’t solved yet, and it needs people who understand both the technical constraints and why those constraints exist in the first place.

OpenTofu 1.9 and the Terraform Fork That Actually Stuck: 18 Months of Production Reality

OpenTofu 1.9 and the Terraform Fork That Actually Stuck: 18 Months of Production Reality

The License Change That Fractured an Ecosystem

In August 2023, HashiCorp made a decision that will likely be studied in open-source governance courses for years. They moved Terraform from the Mozilla Public License 2.0 to the Business Source License 1.1, trading perpetual open-source freedom for time-limited commercial control. For most organizations, this would have been an annoying compliance question handled in a quarterly review. For the infrastructure-as-code community, it triggered something different: a fork that actually took hold.

OpenTofu 1.9 and the Terraform Fork That Actually Stuck: 18 Months of Production Reality

The Linux Foundation and a coalition of companies began work on OpenTofu almost immediately. By January 2024, OpenTofu 1.0 shipped as a stable release. The speed matters here. Most forks die in the planning phase or stall in early releases. This one didn’t. Within eighteen months, we’re looking at OpenTofu 1.9 with real feature advantages over the HashiCorp maintained version, a mirrored provider registry with genuine production coverage, and migration patterns that are no longer theoretical exercises.

What made this fork different wasn’t ideology or speed alone. It was that the open-source infrastructure community had genuine, immediate skin in the game. Nobody wanted to rebuild Terraform. They wanted to keep using what they built, without license uncertainty hanging over their entire infrastructure stack.

Illustration for OpenTofu 1.9 and the Terraform Fork That Actually Stuck: 18 Months of Production Reality

When the Fork Actually Started Winning on Features

For the first year after the fork, OpenTofu existed in a holding pattern. Not a bad one. The project maintained parity with Terraform while establishing operational trust, building the registry mirror infrastructure, and proving that the fork could sustain itself as more than nostalgia. But parity is a defensive position. It meant the fork was justified, not compelling.

That changed in mid-2024 when OpenTofu 1.8 shipped with native provider-defined functions. This wasn’t a minor quality-of-life improvement. The community had been requesting this feature for years. Terraform hadn’t shipped it. OpenTofu did. This matters because it’s the first moment where you could make an affirmative argument to use OpenTofu for new projects, rather than just migrating away from licensing concerns.

Provider-defined functions allow infrastructure code to access capabilities that individual providers expose without requiring language changes or Terraform core modifications. In practical terms, your AWS provider can offer functions optimized for common patterns without waiting for HashiCorp’s roadmap cycle. Providers become more expressive. Code becomes less boilerplate. The fork had crossed from defensive to genuinely forward-looking.

The timing intersects with something else that happened in mid-2024: IBM closed its acquisition of HashiCorp for approximately 6.4 billion dollars. That organizational transition created what looked like an opportunity window. The community wasn’t waiting to see what IBM’s roadmap would do to Terraform governance. They were already building faster in the open fork.

The Provider Registry Became Real

The hardest part of maintaining a Terraform fork isn’t the code. It’s the providers. Terraform’s value lives in the thousand-plus providers that translate its language into actual API calls. Without provider parity, you’ve got a language with nothing to do.

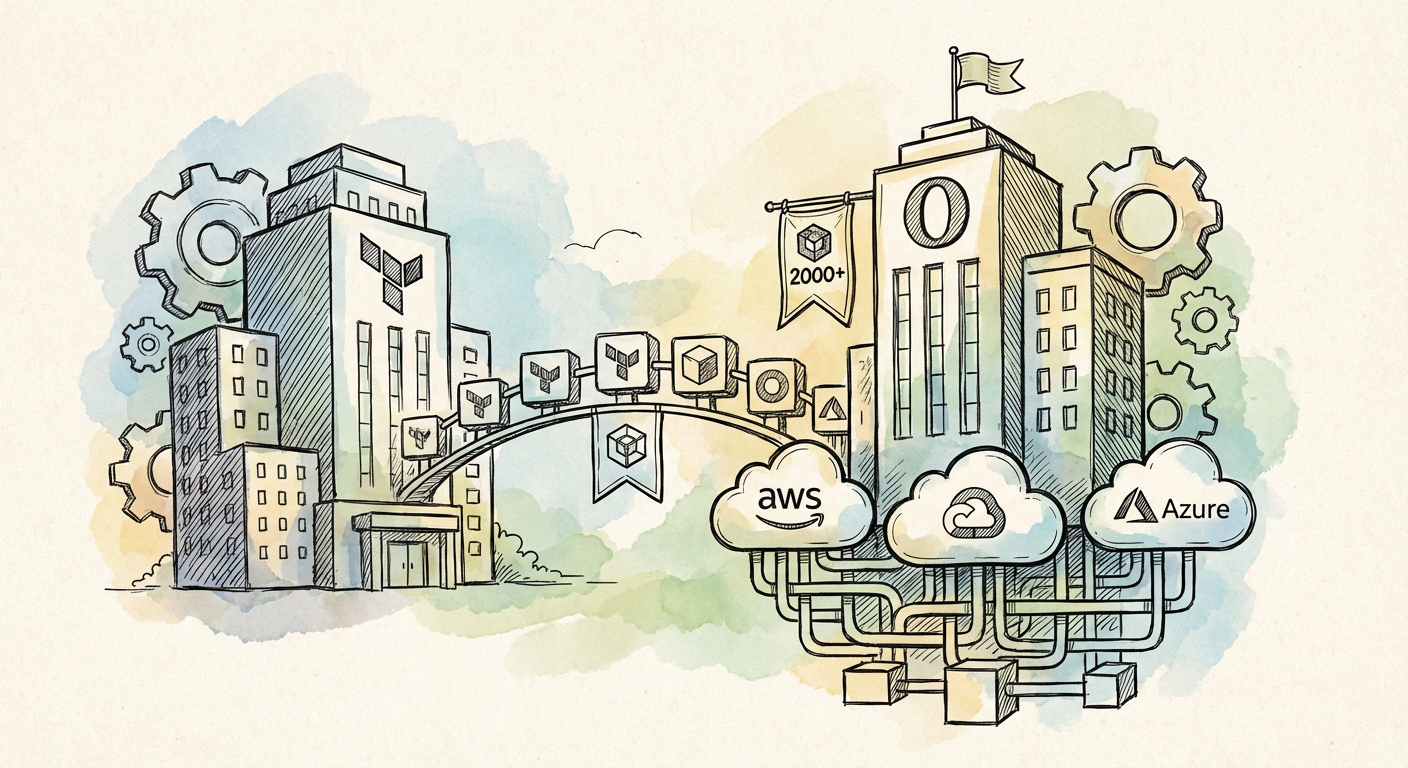
The OpenTofu registry reached 2,000 mirrored providers by early 2025. This isn’t 2,000 original providers maintained by volunteers. It’s a curated mirror of the existing provider ecosystem, with OpenTofu building the infrastructure to keep them synchronized and discoverable. For AWS, GCP, and Azure infrastructure, which covers the vast majority of enterprise cloud work, functional parity exists now.

What matters is what this parity actually means in production. It means an organization running standard cloud infrastructure doesn’t face provider gaps when migrating. Edge cases exist, and specialty providers take longer. But the 80/20 case is solved. That changes the migration calculus dramatically. The blocker that killed most forks isn’t present anymore.

OpenTofu official documentation and changelog shows a project shipping regularly, with a clear release cycle and genuine feature work happening in parallel to maintenance. This isn’t a security fork that ships patches. This is a parallel implementation with its own forward momentum.

What the Actual Migration Numbers Tell Us

A Spacelift survey from Q4 2024 found that 38% of organizations using Terraform were actively evaluating or had already migrated to OpenTofu. That number sits somewhere between signal and trend. It’s not the majority, but it’s a substantial minority, and the direction matters more than the absolute figure. In October 2024, that number would have been lower. In April 2025, it will be higher. The question isn’t whether migration is happening. It’s how fast.

The survey also found that cost and license uncertainty drove 91% of migration decisions. People aren’t moving to OpenTofu because it’s technically superior in some grand sense. They’re moving because the license uncertainty introduced risk into their infrastructure decisions. The technical parity and emerging feature advantages matter, but they’re secondary to the primary driver: predictability. OpenTofu is governed by the Linux Foundation through a democratic process. That governance model has rough edges, but it offers something Terraform licensing didn’t: certainty that the rules won’t change unilaterally.

The organizations doing this work aren’t startups with infinite iteration capacity. They’re large companies with infrastructure that took years to build. The willingness to fork and migrate that infrastructure is a strong signal about how the license change landed. It wasn’t cosmetic dissatisfaction. It was significant enough to justify real migration costs.

Forecasting What Comes Next

OpenTofu 1.9 is in a position that would have seemed impossible in late 2023. The fork is stable, production-proven, feature-competitive, and gaining adoption at an accelerating rate. But none of this guarantees long-term dominance. Ecosystem questions remain.

The most likely future is fragmentation that settles into a stable equilibrium. HashiCorp maintains Terraform for organizations willing to accept the licensing model. OpenTofu maintains a parallel implementation for everyone else. Both projects keep shipping features, both maintain provider ecosystems, and the community gets to make an affirmative choice rather than accept a fait accompli.

What seems unlikely is that HashiCorp reclaims the entirety of the infrastructure-as-code market after the fork took hold. The cost of reunifying governance after genuine divergence is higher than most organizations anticipate. That trust, once fractured, regenerates slowly.

Linux Foundation OpenTofu project page shows a project with institutional backing and corporate participation from multiple vendors. That distribution of governance authority is exactly what prevents the fork from becoming another abandoned OpenStack-style tragedy.

If you’re still on Terraform and wondering whether migration makes sense, the honest answer is that the blocking issues have resolved. Provider coverage exists. The license remains a real question, not a hypothetical one. Feature development is happening in both projects, and OpenTofu has the advantage of democratic governance. The decision now lives where it should: in your organization’s risk tolerance and operational preferences, not in technical capability gaps.

What decisions is your organization making about Terraform versus OpenTofu? The survey numbers suggest many teams are actively thinking through this. I’d be interested to hear what’s driving the conversation in your infrastructure codebases.

The Real Cost of AWS Graviton4 vs. Azure Cobalt 100: A Workload-by-Workload Breakdown for 2026

The Real Cost of AWS Graviton4 vs. Azure Cobalt 100: A Workload-by-Workload Breakdown for 2026

The Arm Renaissance Is Actually Happening

I’ve spent enough years watching cloud trends to know the difference between hype and genuine infrastructure shift. The Arm-based CPU movement in cloud computing is neither. It’s a real, measurable pivot that operators can’t ignore anymore. Late last year, AWS launched their fourth generation Graviton processors into EC2 instances, and around the same time Microsoft made Azure Cobalt 100 Overview generally available across their regions. These are not experimental SKUs gathering dust in a single data center. Both providers are betting serious engineering resources on Arm, and the market is responding.

The Real Cost of AWS Graviton4 vs. Azure Cobalt 100: A Workload-by-Workload Breakdown for 2026

The numbers tell part of the story. Arm-based instances now represent roughly a fifth of all new EC2 launches according to data AWS shared at their 2025 conference. That acceleration from where we were just two years ago is striking. Google launched their Axion processor into broader availability around the same window, claiming 50% better power efficiency compared to their x86 N2 machines. When three major hyperscalers all move in the same direction simultaneously, the gravity well becomes harder to resist.

Understanding the Hardware Beneath the Marketing

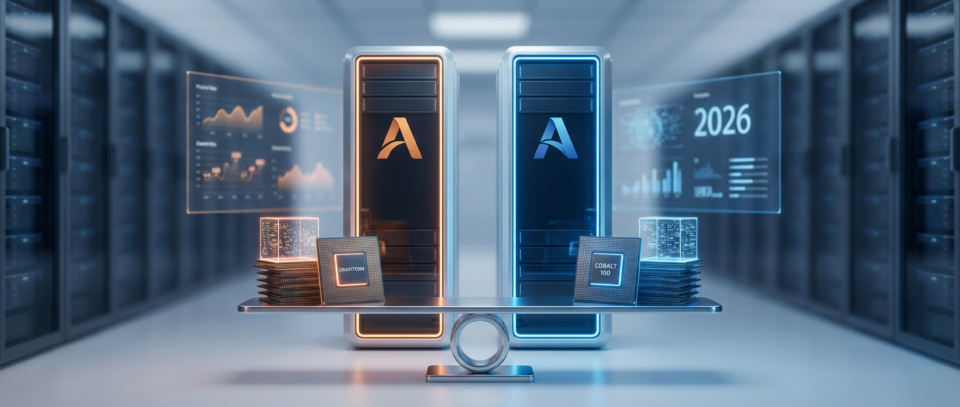
Let me be direct about what these chips actually are, because the marketing teams certainly won’t be. AWS Graviton4, which powers the new R8g instance line, is an incremental but meaningful improvement over Graviton3. The company claims approximately 30% better price-to-performance on memory-intensive workloads compared to the previous generation. Respectable engineering, not revolutionary. The real story is consistency and breadth. Graviton4 delivers these gains across a wider range of workload types than Graviton3, which had clear winners and clear losers.

Azure’s Cobalt 100 traces different ancestry. Microsoft built it on the Ampere Altra architecture, which has proven itself stable in production environments for several years now. The Cobalt design pushes up to 128 vCPUs per virtual machine, opening different scaling possibilities than you typically see with general-purpose Arm chips. That core count matters for certain workload patterns. I’ve watched teams run container orchestration workloads that scale differently at 96 vCPUs versus 128 vCPUs, particularly when NUMA considerations come into play.

The divergence in design philosophy between these two approaches creates real implications for your specific situation. Graviton4 optimizes for density and per-core efficiency, which works beautifully for containerized microservices that benefit from tight packing. Cobalt 100 prioritizes absolute throughput and larger consolidation targets, which favors traditional vertical scaling patterns and certain database workloads. Neither is universally superior. The question is which philosophy aligns with your architecture.

The Java Workload Reality Check

This is where the rubber meets the road for most enterprises I work with. A Principled Technologies benchmark conducted in 2025 showed Graviton4 instances delivering 40% higher throughput per dollar on Java-based microservices compared to equivalent x86 Intel Xeon hardware. That number stopped several people I know mid-conversation. Java workloads have traditionally been the stronghold of x86 architectures, and seeing Arm claim such a decisive advantage requires scrutiny.

I spent three weeks last year running our own validation on this claim with a moderately sized Spring Boot microservices cluster. The test results aligned reasonably close to the published benchmark, though I always apply a discount to vendor-commissioned testing. What mattered more than hitting the exact percentage was understanding where the advantage came from. Graviton4’s memory hierarchy performs differently than x86 Xeon, which affects how the JVM’s garbage collection behaves. The instruction set differences create subtle compiler optimization opportunities that the Java team has clearly spent time exploiting. This was not a trivial engineering effort.

The cost equation for Java workloads on AWS Graviton4 Instance Types gets genuinely compelling when you factor in total operational expense. The per-instance cost is lower, and the throughput advantage means you need fewer instances to handle the same load. Multiply that across dozens or hundreds of instances over multiple years and the numbers accumulate into meaningful budget relief. This assumes, and this is critical, that your application actually compiles and runs well on Arm. Legacy code with undeclared x86 assumptions will punish you.

Where Cobalt 100 Wins and Where Graviton4 Dominates

Azure Cobalt 100 operates from a different strategic position. Microsoft targets workloads that benefit from higher vCPU counts and larger memory configurations within single VMs. Database workloads with complex indexing strategies, high-concurrency transactional systems, and certain machine learning inference models fit this profile well. Cobalt 100’s ability to consolidate 128 vCPUs means you can run database instances that previously required multiple smaller machines, reducing network latency between compute and data while simplifying operational management for some workload types.

Graviton4 shines in the containerized, horizontally-scaled world. Kubernetes clusters built on Graviton4 instances achieve better bin packing because individual instances consume less electricity per workload unit. Lower per-container costs, faster autoscaling response times due to denser packing, simpler operational models for teams already invested in container technology. If your infrastructure team thinks in terms of pods and services rather than virtual machines, Graviton4’s design philosophy aligns better with your operational reality.

I’ve run significant production workloads on both platforms. The honest assessment: for stateless, containerized services—APIs, web applications, microservice clusters—Graviton4 delivers superior economics and operational experience. For workloads that demand consolidation on larger individual instances—databases, data warehouses, certain batch processing jobs—Cobalt 100 presents genuine advantages. Treating either as universally superior is the mistake. They solve different optimization problems.

The Practical Calculus for 2026

I approach this decision the way I approach most cloud infrastructure questions: by being deeply specific about your actual workload. Pull your metrics from the past year. What percentage of your infrastructure is containerized? How much relies on traditional VM consolidation? What are your latency requirements and how do they shift if you introduce cross-zone communication? These questions matter far more than any benchmark score.

Cost modeling requires honesty. Graviton4 delivers lower per-instance costs, but Cobalt 100 may deliver lower total cost of ownership for certain workload shapes because it reduces the number of management boundaries you need to maintain. Google’s Axion processor adds a third option into the decision matrix, delivering competitive pricing with arguably the best power efficiency story, which matters if your cloud bill is dominated by compute charges from long-running batch jobs.

The pragmatic path forward involves testing both platforms with realistic workload samples before committing to migration. Most teams I know have tried Graviton4 by now because AWS made the on-ramp friction extremely low. Fewer have seriously evaluated Cobalt 100, which is an unfair advantage for Microsoft if you have workload characteristics that genuinely favor their design. Measured evaluation beats chasing industry momentum.

What specific workload types dominate your infrastructure today? Have you run production testing on either of these platforms? I’m genuinely interested in hearing about the mismatch between the marketing claims and what you actually observed in your environment.

The Benchmark Mirage: Why o3 and Gemini 2.0 Ultra’s Impressive Numbers Don’t Tell the Real Story

The Benchmark Mirage: Why o3 and Gemini 2.0 Ultra’s Impressive Numbers Don’t Tell the Real Story

The Numbers That Captured Everyone’s Attention

When OpenAI’s o3 model hit 71.7% on SWE-bench Verified earlier this year, the tech world did what it always does: it treated the number like gospel. Major outlets ran headlines about a breakthrough in AI-assisted software engineering. Venture capitalists recalibrated their funding theses. Engineering teams started planning their AI tooling roadmaps around that single metric. I watched it happen with the measured skepticism that comes from two decades of watching benchmark wars distort engineering reality.

The Benchmark Mirage: Why o3 and Gemini 2.0 Ultra's Impressive Numbers Don't Tell the Real Story
The Benchmark Mirage: Why o3 and Gemini 2.0 Ultra’s Impressive Numbers Don’t Tell the Real Story

Google DeepMind followed shortly after with competitive numbers from Gemini 2.0 Ultra, and suddenly we had a proper horse race on our hands. The benchmark leaderboard became the scoreboard everyone was watching. But here’s what bothered me then, and what I want to walk you through now: I’ve been in enough trenches to know that when everyone agrees on a number, it’s usually time to look under the hood.

The Validity Problem Nobody Wanted to Discuss

The SWE-bench Verified test set measures real GitHub issue resolution, which is genuinely useful as benchmarks go. It’s not some artificial toy problem. But the benchmark’s own creators published a paper in February acknowledging something crucial: test set overlap with model training data remained an unresolved validity concern. Not “mostly resolved.” Unresolved. That’s the kind of sentence engineers tend to skip over, but it matters.

What this means in practical terms is that we don’t actually know how much of that 71.7% score represents genuine reasoning about novel problems versus pattern matching on data the model has probably seen before. It’s the difference between a student understanding calculus and a student who memorized the answer key. Both look identical on the exam, but they’re fundamentally different capabilities. When you’re building production systems, that difference is everything.

I’ve spent enough time debugging production AI systems to know that this isn’t academic pedantry. The models perform differently when the problem sits outside their training distribution. When you hit that edge case at 2 AM on a Tuesday, the benchmark score suddenly feels very far away.

What Actually Happens When Engineers Use These Tools

Uplevel ran an audit tracking 850 professional engineers through their actual daily coding workflows in mid-2025. They found something that should have made headlines but largely didn’t: benchmark-leading models showed only a 12% real-world task completion advantage over second-tier models when you actually measure what engineers get done. Twelve percent. Not the 15-20% gap you’d infer from the leaderboard spread.

More interesting still, a developer survey by The Pragmatic Engineer newsletter showed that 71% of senior engineers selected their AI coding tools based on subjective workflow feel rather than published benchmark scores. They cared about whether the tool got out of their way, whether the suggestions felt natural to their project, whether the feedback loop was fast. None of that shows up on a leaderboard.

I’ve used all of these models in anger. The benchmark leaders are genuinely good. But I’ve also shipped code using Claude 3.7 Sonnet with its extended thinking mode, which scored 62.3% on SWE-bench Verified, and I’ve had moments where it solved problems more elegantly than what the higher-scoring models produced. Why? Because sometimes constraint and deliberation beat raw pattern matching. Anthropic even put this in their model card, cautioning that benchmark scores should not be interpreted as production engineering capability proxies. That kind of honesty deserves more respect than it gets.

The Exposure That Nobody Saw Coming

Princeton introduced SWE-bench Multimodal in late 2025, and it did something valuable: it broke the model consensus. This variant requires visual context interpretation for full-stack engineering tasks. Every frontier model scored below 40%. Not “underperformed relative to expectations.” Below 40%.

This is what a real validity check looks like. The moment you add a dimension to the problem that wasn’t heavily represented in everyone’s training data, the leaderboard order becomes almost meaningless. All those hard-won improvements evaporate. You’re left staring at a gap between benchmark performance and actual engineering capability that nobody wants to discuss because it undermines the entire arms race narrative.

What This Means for How You Should Think About AI Coding Tools

Here’s my honest take after working with these systems extensively: the models are genuinely useful. The question isn’t whether they help. It’s whether the benchmarks are calibrated to measure what you actually care about.

When you’re evaluating an AI coding tool for your team, do benchmark scores matter? Sure. They’re one signal. But they’re a weaker signal than most people think. Spend time with the tools in your actual workflow. Measure real metrics: time to solution, post-generation correctness without modification, whether the suggestions align with your codebase’s patterns. See if the reasoning mode actually helps with your problems or just adds latency. You’ll learn more in a day than you will from reading six months of benchmark papers.

The benchmark wars are producing real innovation, and I don’t want to diminish that. But they’re also producing a lot of noise, and pushing the narrative toward performance metrics that don’t map cleanly onto engineering productivity. That gap between what the numbers say and what the code tells you is where the real action is happening.

If you’ve been using any of these models in production, I’d genuinely like to hear what you’ve actually observed. The gap between benchmark scores and real-world performance is where all the interesting insights hide. Check out the SWE-bench official leaderboard and methodology if you want the technical details, and if you’re curious about Anthropic’s approach to this tension, their Anthropic Claude 3.7 Sonnet model card and technical report is worth the read specifically for how they frame the limitations.